Search Console's Page Indexing Report: What Each Reason Means and Which to Ignore
Harry Strick
Ranked AI
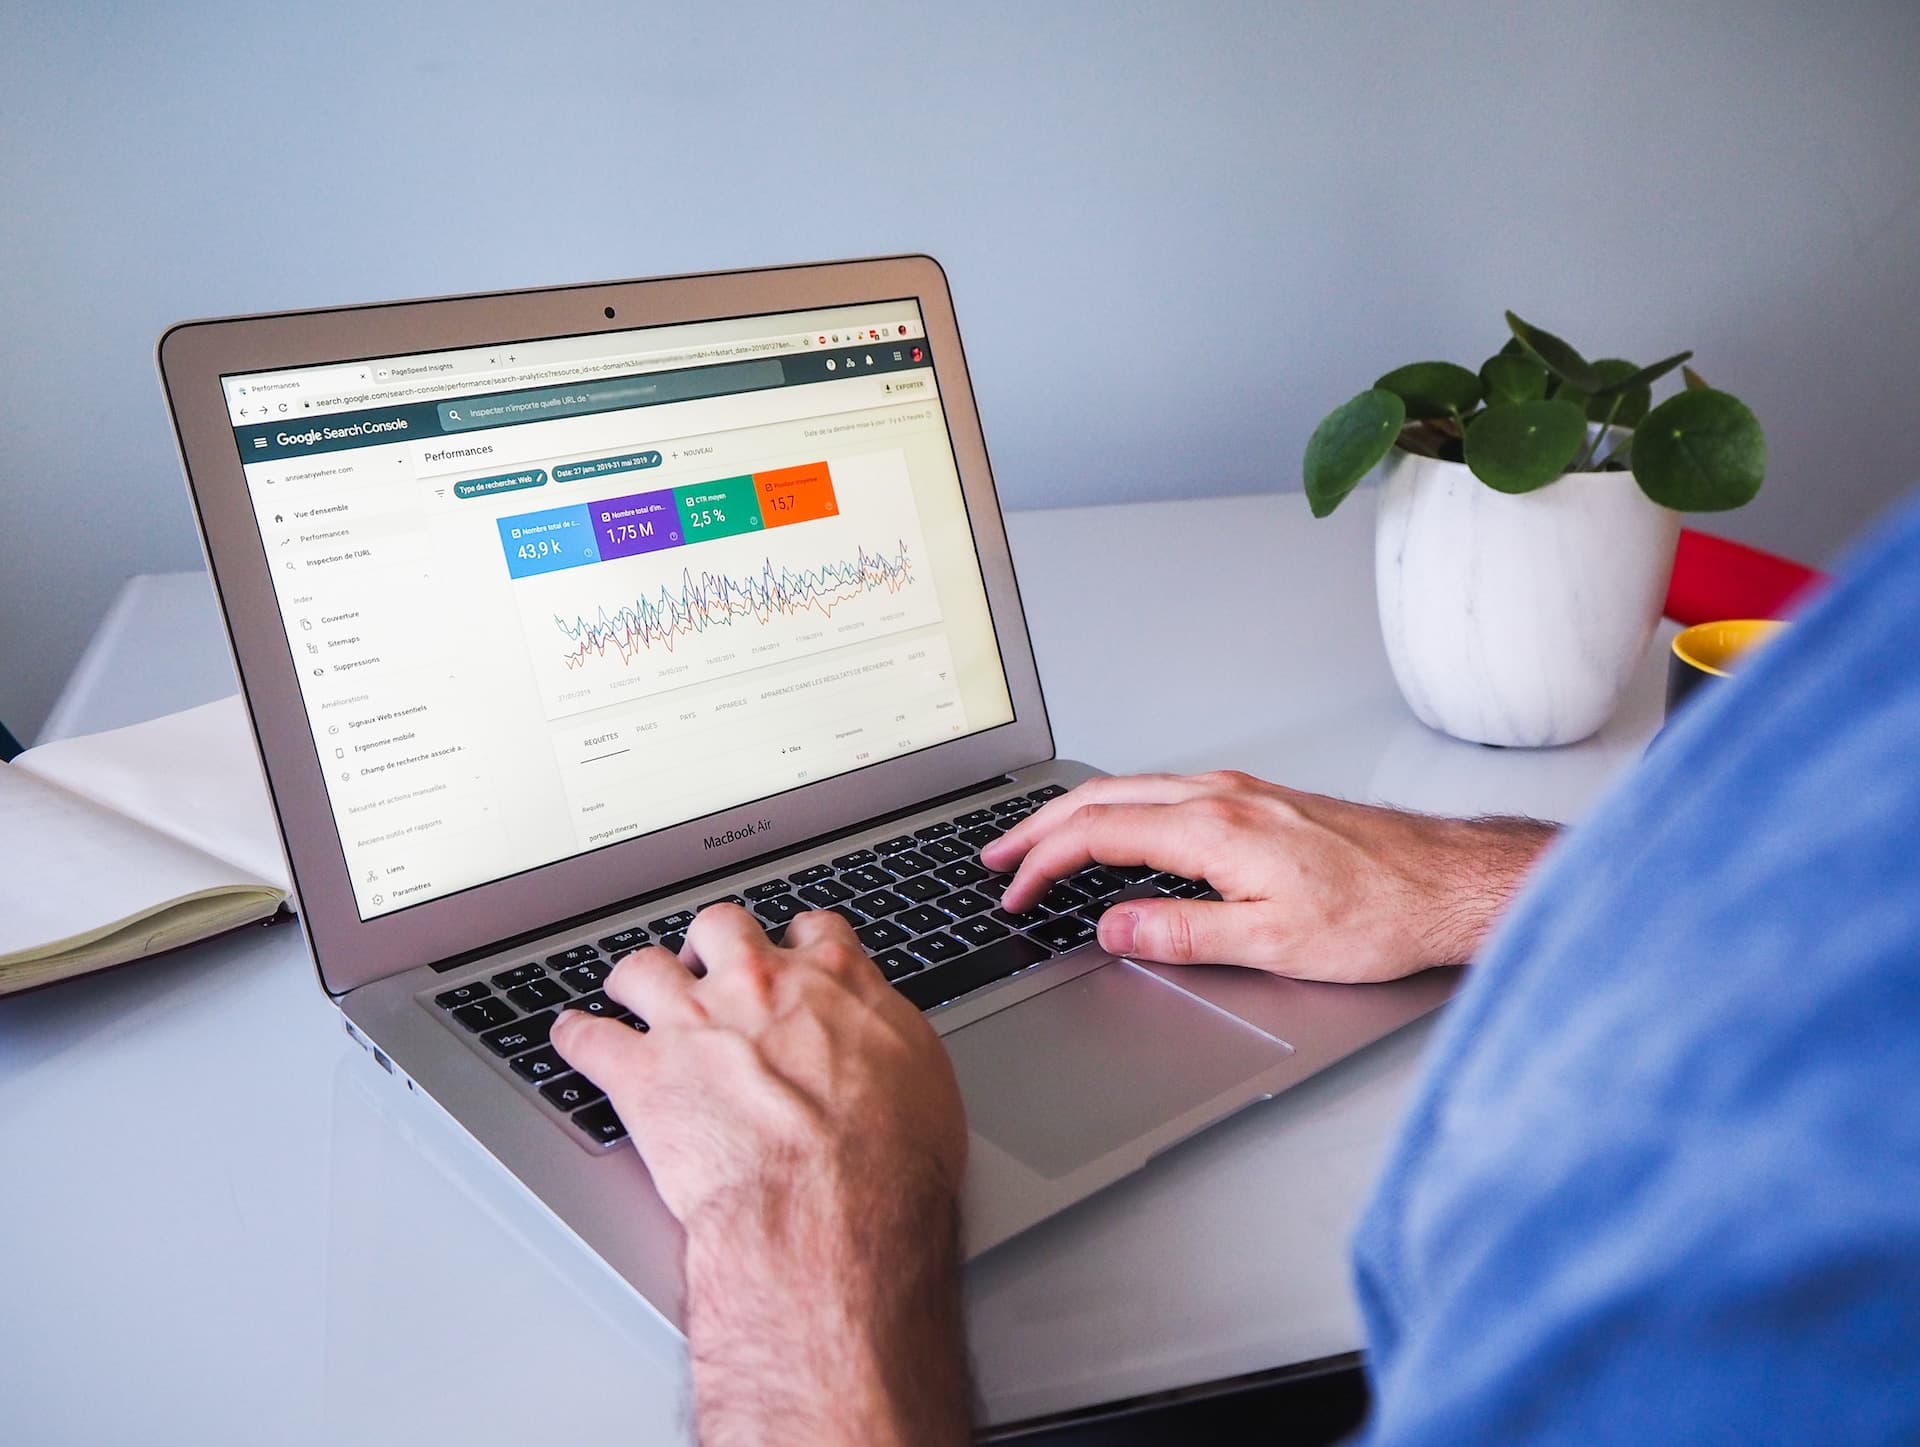
The Page indexing report in Search Console lists every URL Google knows about on your site and says whether it is indexed and, if not, why. The number that alarms people, the grey "not indexed" count, is usually mostly fine. Google's own help text says so in several places: duplicates, redirects, blocked pages and pages you marked noindex are supposed to be there. The job is to find the handful of rows that represent pages you actually want in Search and are not.
Below is every reason the report can show, in Google's own wording, with what it means and whether it needs you.
First, the mindset
Google's help page for the report sets expectations plainly: your goal is "to get the canonical version of every important page indexed", you should not expect 100% coverage, and "Not indexed is not necessarily bad". It also warns not to expect the totals to match your own count of pages, because Google counts URLs it has discovered, including variants you never meant to publish.
So before reading any reason, decide what you care about. Usually that is the pages in your sitemap. The report lets you filter to "All submitted pages", and that view is where the real problems live.
Leave alone: working as intended
These reasons describe URLs Google is deliberately not indexing, and for a healthy site they are the majority.
Alternate page with proper canonical tag. The URL points to a canonical that is indexed. Nothing to do. (Google notes that alternate language pages are not detected here, so hreflang variants will not show under this.)
Duplicate without user-selected canonical. Google found two very similar pages, you did not say which is primary, and it chose one. Working as intended. The only question is whether it chose the one you would have chosen; inspect the URL to see the Google-selected canonical and, if you disagree, add an explicit canonical tag.
Page with redirect. The URL redirects, so the target gets indexed instead. Expected after any migration or URL change.
URL marked 'noindex'. Google saw your noindex and obeyed. The help text literally says "congratulations" if that was the intent. The only check: make sure the noindexed URLs are the ones you meant, not a template accident that hit a whole section.
URL blocked by robots.txt. Blocked from crawling by your rules. Fine if intentional. Two things to know: robots.txt does not guarantee a page stays out of the index if Google finds it another way, and to keep a page out for certain you should unblock it and use noindex instead.
Not found (404). Google tried a URL that no longer exists. If the page was deleted on purpose and has no replacement, 404 is the correct response and Google says these are "not necessarily a problem". Googlebot will keep trying it for a while, less and less often. If the page moved, redirect it.
Check: fine or not, depending on the page
Crawled, currently not indexed. Google fetched the page and decided not to index it, for now. The help text says it "may or may not be indexed in the future" and that resubmitting does not help. In practice this is Google's quality judgement: thin pages, near-duplicates, tag archives, pages with nothing a reader would search for. If an important page sits here for weeks, the fix is on the page itself (more substance, better internal links to it), not in Search Console.
Discovered, currently not indexed. Google knows the URL exists but has not crawled it, usually because it expected crawling to overload your site and rescheduled. On a small site this often means a new page waiting its turn; give it time. On a large site with thousands of these, it points to crawl capacity: slow responses, too many low-value URLs, or weak internal linking to the pages that matter.
Duplicate, Google chose different canonical than user. You declared a canonical and Google disagreed, indexing a different URL instead. Google's explanation is that the page you declared as canonical is not actually similar to this one, so it cannot be its duplicate. Look at all three URLs (the tested page, your canonical, Google's choice). Either your canonical tag is wrong, or the pages are not as similar as you think and should be differentiated.
Soft 404. The page returns a 200 status but looks like a "not found" page to Google: empty results, a "no products" message, a placeholder. Return a real 404 for genuinely missing pages, or add real content if the page is supposed to exist. The URL Inspection tool's screenshot shows you what Google saw.
Blocked due to access forbidden (403). Googlebot got a 403. Google points out that Googlebot never sends credentials, so a 403 means your server or firewall is refusing it specifically. Common causes are bot-protection rules on a CDN or hosting firewall. Allow verified Googlebot requests.
Blocked due to unauthorized request (401). The page asks for a login. Correct for private pages. If it is a public page, something in front of it is demanding authentication by mistake.
URL blocked due to other 4xx issue. A 4xx that is not 401, 403 or 404. Rare; use URL Inspection to see the exact response.
Fix now: errors on pages you want indexed
Server error (5xx). Your server failed when Google asked for the page. A few scattered 5xx rows after a deploy are noise. A persistent pattern means an overloaded server, a broken template or a hosting problem, and it will drag crawling down across the site.
Redirect error. A redirect chain that was too long, a loop, a URL that grew past the maximum length, or a bad URL in the chain. These usually come from stacked rules after a migration. Trace the chain with any redirect checker and collapse it to one hop.
Indexed, though blocked by robots.txt. This appears under warnings rather than errors. The page is in the index but Google cannot read it, so the result shows with no snippet. If you want it indexed, unblock it. If you want it out, unblock it and add noindex; blocking alone will never remove it.
The three questions that resolve most of the report
Is the page in my sitemap? If not, and it is one of the alternate, duplicate, redirect or noindex reasons, it is almost certainly fine. The report exists partly to show you URLs you did not know Google had found.
Can Google fetch it? Run the live test in URL Inspection. It follows redirects and shows the rendered page and the HTTP response. Google notes one limit: the live test does not check duplicate or canonical conditions, so a clean live test can still sit under a duplicate reason.
Is the page worth indexing? Honest question. A tag archive with two posts, a location page that differs from its sibling by one word, a product variant for every colour: Google's "crawled, currently not indexed" is often a correct call about pages like these. The fix is to make the page worth it or to stop publishing it, not to keep requesting indexing.
Validation, and what "fixed" means
When you resolve an issue, the report offers a Validate Fix button. Google re-checks the affected URLs over roughly two weeks and reports Passed or Failed. Two things catch people out. First, Google considers a URL "fixed" for validation if it is no longer available at all (removed, noindexed, redirected), so a validation can pass without the page being indexed. Second, validation is optional; Google will recrawl on its own schedule anyway, and for a handful of URLs the Request Indexing button in URL Inspection is faster.
Patterns that mean something bigger
A sudden drop in indexed pages with no matching rise in errors usually means you blocked something: a new robots.txt rule, a noindex on a template, or a login wall. Look for a site-wide change on that date.
Far more not-indexed than indexed pages points at one of three things, per Google: a robots.txt rule blocking large sections, lots of redirecting URLs, or a sitemap full of URLs that are blocked or noindexed.
A spike in one error type after a release is a template bug. Fix the template, validate, move on.
Questions people ask
Why does Google keep crawling a page I deleted years ago?
Because it once knew the URL and keeps checking in case the error was temporary. Google says there is no way to tell it to forget a URL permanently; it simply crawls it less and less often. It is harmless.
How long does indexing take after I fix something?
Anywhere from days to weeks. Crawl frequency depends on how often Google thinks a page changes and how much capacity it allocates to your site. Request Indexing for a few important URLs; for the rest, make sure they are in the sitemap and linked internally, then wait.
Should I try to get every page indexed?
No. Google's help text says the goal is the canonical version of every important page. Duplicates, filters, internal search results and thin archives are better left out, and often Google leaves them out for you.
If you would rather not read the report every month
Interpreting this report is a small, recurring task that is easy to skip and easy to overreact to. It is part of the monthly technical audit in Ranked's SEO service, alongside the fixes for the rows that actually matter. If a reason in your report has you worried and you want a second opinion, send us a screenshot.
Want this handled for you?
Weekly content, optimization, backlinks and AI search indexing - starting at $99 per month.